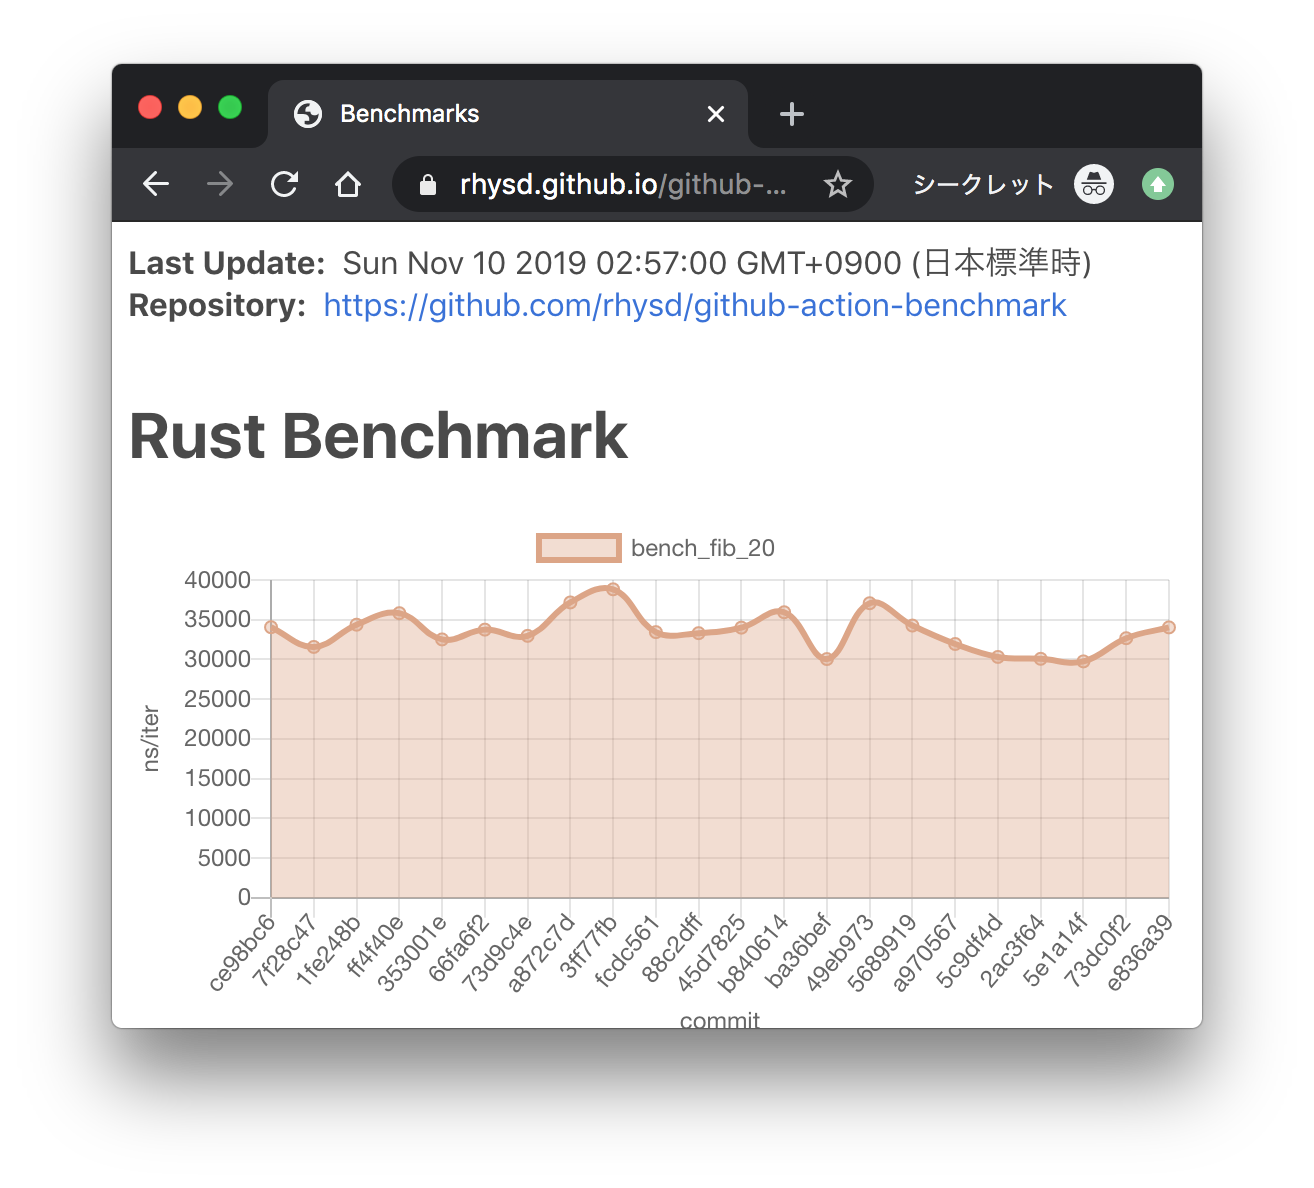
Adds availability-write regression tests.
The results for the `availability-distribution` subsystem are volatile,
so I had to reduce the precision of the test.
Fixes https://github.com/paritytech/polkadot-sdk/issues/3528

```rust
latency:
    mean_latency_ms = 30 // common sense
    std_dev = 2.0 // common sense
n_validators = 300 // max number of validators, from chain config
n_cores = 60 // 300/5
max_validators_per_core = 5 // default
min_pov_size = 5120 // max
max_pov_size = 5120 // max
peer_bandwidth = 44040192 // from the Parity's kusama validators
bandwidth = 44040192 // from the Parity's kusama validators
connectivity = 90 // we need to be connected to 90-95% of peers
```
### What's been done
- `subsystem-bench` has been split into two parts: a cli benchmark
runner and a library.
- The cli runner is quite simple. It just allows us to run `.yaml` based
test sequences. Now it should only be used to run benchmarks during
development.
- The library is used in the cli runner and in regression tests. Some
code is changed to make the library independent of the runner.
- Added first regression tests for availability read and write that
replicate existing test sequences.

### How we run regression tests
- Regression tests are simply rust integration tests without the
harnesses.
- They should only be compiled under the `subsystem-benchmarks` feature
to prevent them from running with other tests.
- This doesn't work when running tests with `nextest` in CI, so
additional filters have been added to the `nextest` runs.
- Each benchmark run takes a different time in the beginning, so we
"warm up" the tests until their CPU usage differs by only 1%.
- After the warm-up, we run the benchmarks a few more times and compare
the average with the exception using a precision.

### What is still wrong?
- I haven't managed to set up approval voting tests. The spread of their
results is too large and can't be narrowed down in a reasonable amount
of time in the warm-up phase.
- The tests start an unconfigurable prometheus endpoint inside, which
causes errors because they use the same 9999 port. I disable it with a
flag, but I think it's better to extract the endpoint launching outside
the test, as we already do with `valgrind` and `pyroscope`. But we still
use `prometheus` inside the tests.

### Future work
* https://github.com/paritytech/polkadot-sdk/issues/3528
* https://github.com/paritytech/polkadot-sdk/issues/3529
* https://github.com/paritytech/polkadot-sdk/issues/3530
* https://github.com/paritytech/polkadot-sdk/issues/3531

---------

Co-authored-by: Alexander Samusev <41779041+alvicsam@users.noreply.github.com>
This PR removes the configuration of subsystem benchmarks via CLI
arguments. After this, we only keep configurations only in yaml files.
It removes unnecessary code duplication
1. Benchmark results are collected in a single struct.
2. The output of the results is prettified.
3. The result struct used to save the output as a yaml and store it in
artifacts in a CI job.

```
$ cargo run -p polkadot-subsystem-bench --release -- test-sequence --path polkadot/node/subsystem-bench/examples/availability_read.yaml | tee output.txt
$ cat output.txt

polkadot/node/subsystem-bench/examples/availability_read.yaml #1

Network usage, KiB                     total   per block
Received from peers               510796.000  170265.333
Sent to peers                        221.000      73.667

CPU usage, s                           total   per block
availability-recovery                 38.671      12.890
Test environment                       0.255       0.085


polkadot/node/subsystem-bench/examples/availability_read.yaml #2

Network usage, KiB                     total   per block
Received from peers               413633.000  137877.667
Sent to peers                        353.000     117.667

CPU usage, s                           total   per block
availability-recovery                 52.630      17.543
Test environment                       0.271       0.090


polkadot/node/subsystem-bench/examples/availability_read.yaml #3

Network usage, KiB                     total   per block
Received from peers               424379.000  141459.667
Sent to peers                        703.000     234.333

CPU usage, s                           total   per block
availability-recovery                 51.128      17.043
Test environment                       0.502       0.167

```

```
$ cargo run -p polkadot-subsystem-bench --release -- --ci test-sequence --path polkadot/node/subsystem-bench/examples/availability_read.yaml | tee output.txt
$ cat output.txt
- benchmark_name: 'polkadot/node/subsystem-bench/examples/availability_read.yaml #1'
  network:
  - resource: Received from peers
    total: 509011.0
    per_block: 169670.33333333334
  - resource: Sent to peers
    total: 220.0
    per_block: 73.33333333333333
  cpu:
  - resource: availability-recovery
    total: 31.845848445
    per_block: 10.615282815
  - resource: Test environment
    total: 0.23582828799999941
    per_block: 0.07860942933333313

- benchmark_name: 'polkadot/node/subsystem-bench/examples/availability_read.yaml #2'
  network:
  - resource: Received from peers
    total: 411738.0
    per_block: 137246.0
  - resource: Sent to peers
    total: 351.0
    per_block: 117.0
  cpu:
  - resource: availability-recovery
    total: 18.93596025099999
    per_block: 6.31198675033333
  - resource: Test environment
    total: 0.2541994199999979
    per_block: 0.0847331399999993

- benchmark_name: 'polkadot/node/subsystem-bench/examples/availability_read.yaml #3'
  network:
  - resource: Received from peers
    total: 424548.0
    per_block: 141516.0
  - resource: Sent to peers
    total: 703.0
    per_block: 234.33333333333334
  cpu:
  - resource: availability-recovery
    total: 16.54178526900001
    per_block: 5.513928423000003
  - resource: Test environment
    total: 0.43960946299999537
    per_block: 0.14653648766666513
```

---------

Co-authored-by: Andrei Sandu <54316454+sandreim@users.noreply.github.com>
## Why we need it
To provide another level of understanding to why polkadot's subsystems
may perform slower than expected. Cache misses occur when processing
large amounts of data, such as during availability recovery.

## Why Cachegrind
Cachegrind has many drawbacks: it is slow, it uses its own cache
simulation, which is very basic. But unlike `perf`, which is a great
tool, Cachegrind can run in a virtual machine. This means we can easily
run it in remote installations and even use it in CI/CD to catch
possible regressions.

Why Cachegrind and not Callgrind, another part of Valgrind? It is simply
empirically proven that profiling runs faster with Cachegrind.

## First results
First results have been obtained while testing of the approach. Here is
an example.

```
$ target/testnet/subsystem-bench --n-cores 10 --cache-misses data-availability-read
$ cat cachegrind_report.txt
I refs:        64,622,081,485
I1  misses:         3,018,168
LLi misses:           437,654
I1  miss rate:           0.00%
LLi miss rate:           0.00%

D refs:        12,161,833,115  (9,868,356,364 rd   + 2,293,476,751 wr)
D1  misses:       167,940,701  (   71,060,073 rd   +    96,880,628 wr)
LLd misses:        33,550,018  (   16,685,853 rd   +    16,864,165 wr)
D1  miss rate:            1.4% (          0.7%     +           4.2%  )
LLd miss rate:            0.3% (          0.2%     +           0.7%  )

LL refs:          170,958,869  (   74,078,241 rd   +    96,880,628 wr)
LL misses:         33,987,672  (   17,123,507 rd   +    16,864,165 wr)
LL miss rate:             0.0% (          0.0%     +           0.7%  )
```

The CLI output shows that 1.4% of the L1 data cache missed, which is not
so bad, given that the last-level cache had that data most of the time
missing only 0.3%. Instruction data of the L1 has 0.00% misses of the
time. Looking at an output file with `cg_annotate` shows that most of
the misses occur during reed-solomon, which is expected.
* Warn if participated in the losing side of a dispute

* Update naming

* Additionally filter by candidate hash

* Debug zombienet tests

* Update 0002-parachains-disputes.zndsl

* Debug zombienet

* Update node/core/dispute-coordinator/src/initialized.rs

Co-authored-by: Andrei Sandu <54316454+sandreim@users.noreply.github.com>

* Add checking to zombienet tests

---------

Co-authored-by: Andrei Sandu <54316454+sandreim@users.noreply.github.com>